
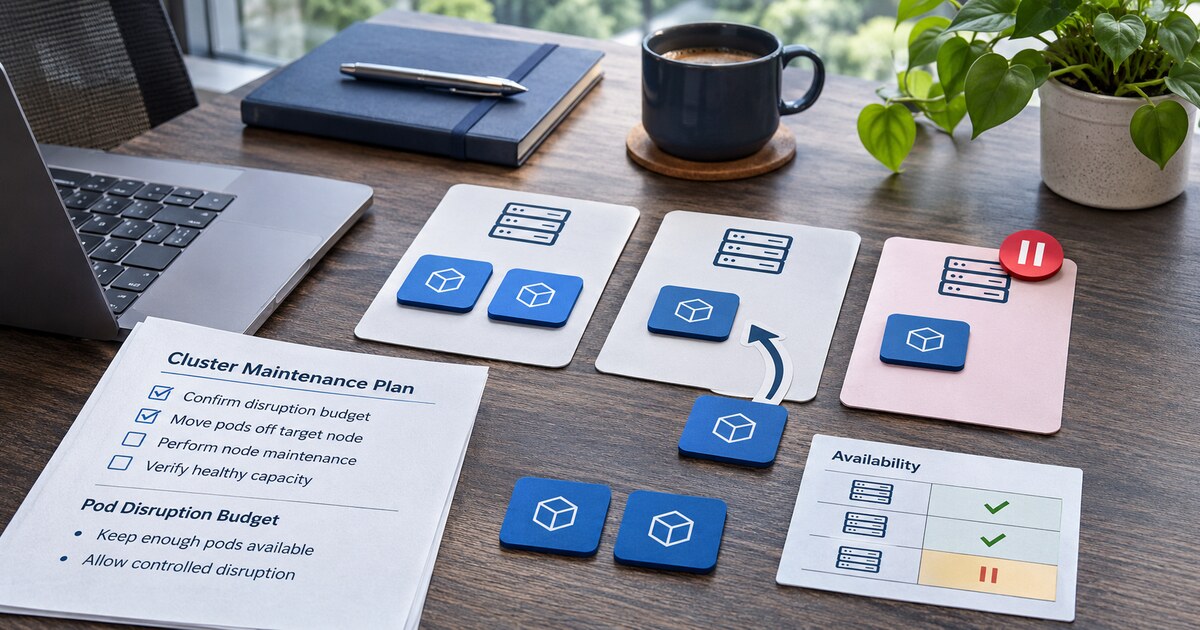
An EKS Pod Disruption Budget, or PDB, limits how many replicas of an application may be unavailable during voluntary disruptions such as a managed node-group update or a deliberate node drain. A useful PDB protects service capacity while still allowing at least one pod to move. It does not create replicas, add spare nodes, fix readiness failures, or protect a workload from involuntary failures such as a node crash.
The practical rule is to design the workload and the budget together. Run enough healthy replicas, spread them across failure domains, reserve capacity for replacements, and set either `maxUnavailable` or `minAvailable` to reflect the service's real tolerance. Then test a drain before the maintenance window. A budget that allows zero voluntary evictions can preserve a policy boundary, but it will also stop an EKS node update until an operator changes the workload or the budget.
What you need to know
- Use PDBs for voluntary evictions; they cannot prevent an unexpected node, network, or application failure.
- Choose either `maxUnavailable` or `minAvailable`, never both in the same PDB.
- Give the scheduler enough replicas, topology spread, and spare capacity to place replacement pods away from the draining node.
- Inspect `disruptionsAllowed` and workload readiness before starting an EKS managed node-group update.
- Treat `PodEvictionFailure` as a signal to diagnose the budget, selector, health, capacity, and taints—not as an automatic reason to force-delete pods.
- Test drains in a safe environment and record a rollback or escalation decision before production maintenance.
What a Pod Disruption Budget actually protects
Kubernetes classifies a planned eviction as a voluntary disruption. Examples include draining a node for maintenance, replacing nodes during an upgrade, or using an administrative process that calls the Eviction API. A PDB tells that eviction process how much of the selected workload must remain available. The API can temporarily reject an eviction when it would violate the budget, allowing the controller time to start and ready a replacement pod.
A PDB is not a high-availability system by itself. It does not increase a Deployment's replica count, ensure that replicas land on different nodes or Availability Zones, or reserve CPU and memory for a replacement. Kubernetes also makes clear that involuntary disruptions cannot be prevented by a PDB, even though unavailable pods caused by those failures count against the budget. If the service has only one replica, a strict budget can block a drain but cannot make the service redundant.
Application rollouts are another important boundary. Unavailable pods during a rollout count when Kubernetes evaluates the budget, but the Deployment or StatefulSet controller is governed by its own update strategy rather than being constrained by the PDB. Align the workload's rolling-update settings with the budget so a rollout does not consume the availability margin that a node drain needs.
| Event | PDB effect | Additional control needed |
|---|---|---|
| Managed node-group drain | Can delay eviction to preserve available replicas | Healthy replicas and schedulable replacement capacity |
| Manual `kubectl drain` | Respected by the Eviction API | One-node-at-a-time procedure and a timeout decision |
| Unexpected node failure | Cannot prevent the failure | Replica spread, recovery capacity, and monitoring |
| Application rolling update | Unavailable pods count, but the rollout controller is not limited by the PDB | Deployment `maxUnavailable` and `maxSurge` settings |
| Single-replica service | Can block voluntary eviction | A second healthy replica or an accepted downtime window |
Continue reading: Kubernetes disruptions and PDBs ↗ · Kubernetes Platform definition
How EKS managed node updates interact with PDBs
During the default managed node-group update strategy, Amazon EKS creates additional nodes, selects old nodes up to the configured maximum unavailable value, cordons a selected node, and drains its pods. The drain uses eviction behavior that must respect applicable PDBs. AWS documents that if pods do not leave within 15 minutes and the update is not forced, the upgrade phase fails with `PodEvictionFailure`.
The minimal update strategy is different: EKS cordons the node group's nodes first, then replaces selected nodes without temporarily increasing total capacity. This can be useful where extra capacity is constrained, but it gives the scheduler less headroom. A PDB that is reasonable under the default strategy can still expose a capacity problem under the minimal strategy if a replacement pod has nowhere healthy to run.
The node group's update setting and the application's PDB answer different questions. The node-group setting controls how many nodes EKS may make unavailable during an update. The PDB controls how many selected application pods may be unavailable during voluntary eviction. Configure both conservatively and assess the combined effect across every workload placed on those nodes.
| Control | What it limits | Operational check |
|---|---|---|
| Node-group maximum unavailable | Nodes updated in parallel | Can each affected workload tolerate pods moving from that many nodes? |
| Pod Disruption Budget | Selected pods unavailable during voluntary eviction | Is `disruptionsAllowed` greater than zero before the update? |
| Deployment update strategy | Pods unavailable or added during application rollout | Will a concurrent rollout consume the same availability margin? |
| Cluster capacity | Where replacement pods can schedule | Is there headroom after requests, affinity, taints, and topology rules? |
Continue reading: Amazon EKS managed node update behavior ↗ · Amazon EKS upgrade runbook
Choose between maxUnavailable and minAvailable
A PDB accepts one availability rule: `maxUnavailable` or `minAvailable`. `maxUnavailable` describes how many selected replicas may be unavailable after an eviction. `minAvailable` describes how many must remain available. Both accept an absolute number or a percentage, but `maxUnavailable` applies when the selected pods share the same associated controller. For common Deployments that scale up and down, `maxUnavailable: 1` is often easier to reason about because the allowed disruption moves with the controller's desired replica count.
Percentage rounding matters. Kubernetes rounds percentage-based `maxUnavailable` values up. With a single desired replica, even `maxUnavailable: 30%` can permit that one replica to be disrupted. Do not assume a percentage creates redundancy. Calculate the result for the workload's minimum and maximum replica counts, including the lowest scale that an autoscaler can select.
Zero-disruption budgets are valid but operationally absolute. `maxUnavailable: 0`, `minAvailable: 100%`, or a minimum equal to the replica count allows no voluntary eviction. Any node hosting a selected pod becomes undrainable until availability increases or the budget changes. Use that policy only when the operating team has an explicit maintenance procedure and authority to coordinate the change.
- Use a selector that matches only the intended workload; an empty selector in `policy/v1` matches every pod in the namespace.
- Check the result at the smallest expected replica count, not only normal peak scale.
- For quorum systems, express the minimum healthy membership the application truly needs.
- Avoid multiple PDBs selecting the same pod; overlapping budgets can cause eviction errors and unclear ownership.
apiVersion: policy/v1
kind: PodDisruptionBudget
metadata:
  name: checkout-api
  namespace: production
spec:
  maxUnavailable: 1
  unhealthyPodEvictionPolicy: AlwaysAllow
  selector:
    matchLabels:
      app.kubernetes.io/name: checkout-api
Continue reading: Kubernetes PDB configuration guidance ↗ · Cloud Computing glossary
Build the workload conditions that make a PDB useful
A budget works only when the application can replace an evicted pod. Begin with at least two replicas for a service that must remain available during a single voluntary disruption. Use topology spread constraints or pod anti-affinity so those replicas do not all settle on one node. For workloads that must survive an Availability Zone event, spread replicas across zones and verify that the node groups and storage design support that placement.
Readiness is central to PDB calculations. Kubernetes considers a pod healthy for the budget when its Ready condition is true. A probe that reports ready before the process can serve traffic makes the budget look safer than the application is; a probe that never becomes ready can leave `disruptionsAllowed` at zero. Tune startup, readiness, and liveness behavior around observed application behavior and keep graceful termination long enough to stop accepting traffic and complete essential work.
The scheduler also needs capacity. Compare pod resource requests with allocatable capacity after the target node is cordoned. Include node selectors, affinities, topology constraints, taints and tolerations, volume-zone restrictions, and DaemonSet overhead. A pending replacement does not restore budget headroom, so a drain can wait indefinitely even though the PDB is expressing the intended availability policy correctly.
| Prerequisite | Failure symptom | Verification |
|---|---|---|
| Multiple replicas | Drain would remove the only serving pod | Compare desired and ready replicas |
| Topology spread | Several replicas disappear with one node | List pod node and zone placement |
| Accurate readiness | Budget reports no safe disruption | Inspect pod conditions and probe events |
| Spare capacity | Replacement remains Pending | Review scheduler events and resource requests |
| Graceful shutdown | Requests fail during termination | Test endpoint removal and termination timing |
Continue reading: Amazon ECS vs EKS comparison
Run a pre-drain inspection
Inspect budgets and workloads before starting the EKS update. The PDB status exposes the expected pod count, currently healthy pods, desired healthy pods, and `disruptionsAllowed`. A non-zero allowed count means the disruption controller currently sees room for that many voluntary disruptions; it is a snapshot, not a promise that the replacement will schedule or become ready.
Map each workload on the target node to a controller and a PDB. Confirm that the budget selector matches the intended labels, the owning controller has the expected replica count, and all required pods are Ready. Review recent events for failed scheduling, image pulls, probe failures, terminating pods, and volume attachment restrictions. Pause application deployments and autoscaling changes when they would make the maintenance result harder to interpret.
Use a dry-run or staged maintenance process appropriate to the environment. `kubectl drain` safely uses the Eviction API and retries rejected evictions, but the exact flags must reflect local DaemonSets, emptyDir data, unmanaged pods, and shutdown requirements. Do not copy a force or deletion flag into production without understanding which workloads it bypasses and what data or availability it can affect.
- Confirm every protected workload has the intended number of Ready replicas.
- Confirm `disruptionsAllowed` is compatible with the update's node concurrency.
- Confirm replacement pods can schedule in another node and, where required, another zone.
- Confirm a named operator owns the stop, rollback, and escalation decision.
- Confirm monitoring covers error rate, latency, readiness, pending pods, and eviction failures during the change.
kubectl get pdb -A
kubectl describe pdb -n production checkout-api
kubectl get deploy,statefulset -n production
kubectl get pods -n production -o wide
kubectl get events -n production --sort-by=.lastTimestamp
Continue reading: Kubernetes guide to safely draining a node ↗ · EKS Pod Identity vs IRSA migration
Diagnose PodEvictionFailure without bypassing the safeguard
When an EKS managed node-group update reports `PodEvictionFailure`, first identify the pod that could not be evicted and the PDB or PDBs that select it. AWS lists an aggressive PDB and multiple PDBs pointing to the same pod among known causes. Kubernetes may also reject an eviction with HTTP 429 when the budget has no room, or with HTTP 500 when overlapping budgets create a misconfiguration.
Next determine why the budget has no room. Common causes include another replica already being unavailable, a replacement pod that is Pending, a readiness probe failure, a selector that matches more pods than intended, a minimum equal to the desired replica count, or a percentage whose rounding produces an unexpected result. Also check whether a workload tolerates the taint used during the update and keeps landing on a node EKS is trying to empty.
Prefer fixing the health, selector, placement, or capacity problem. The EKS force option deletes pods that cannot be evicted and can violate a PDB, so it is a risk acceptance action—not a normal troubleshooting shortcut. Use it only when the workload owner has evaluated the impact, an appropriate maintenance window exists, and the organization has a recovery path for the resulting interruption.
| Observation | Likely cause | Safer response |
|---|---|---|
| `disruptionsAllowed: 0` | Budget margin is exhausted | Restore replica health or revise the planned concurrency |
| Replacement pod Pending | Capacity or scheduling constraint | Add compatible capacity or correct placement constraints |
| Several PDBs select one pod | Overlapping selectors | Assign one clear availability policy to the workload |
| Unhealthy pod cannot leave | Default unhealthy eviction behavior | Fix health or evaluate `AlwaysAllow` for that workload |
| Pod returns to draining node | Overly broad toleration | Correct tolerations and placement rules |
Continue reading: Kubernetes API-initiated eviction ↗ · EKS security best practices
Decide how to handle unhealthy pods
The `unhealthyPodEvictionPolicy` field controls when a running but unready pod may be evicted. The default behavior corresponds to `IfHealthyBudget`: an unhealthy running pod can be evicted only when the application currently has at least the desired healthy count. This gives a struggling pod a chance to recover, but it can also prevent a drain when the pod is stuck in a state such as `CrashLoopBackOff`.
Kubernetes recommends `AlwaysAllow` to support eviction of misbehaving applications during a node drain. Under that policy, running unready pods are considered disrupted and may be evicted regardless of whether the budget is currently satisfied. This improves maintainability, but it does not repair the application and may remove the last running instance of a broken service. Adopt it after application owners understand the tradeoff and recovery behavior.
Document the policy per workload rather than treating it as a cluster-wide default. For a stateless service with several replicas and reliable recovery, `AlwaysAllow` can prevent one broken pod from stopping infrastructure maintenance. A fragile stateful system may require a different intervention, including restoring quorum or repairing storage before any eviction proceeds.
Continue reading: Kubernetes unhealthy pod eviction policy ↗
Use a controlled maintenance runbook
A safe maintenance run starts with a change record that names the node group, Kubernetes version or launch-template change, update strategy, maximum unavailable setting, affected workloads, PDB owners, monitoring window, stop conditions, and rollback or escalation path. Record the baseline of Ready replicas, pending pods, PDB status, application errors, and capacity before touching the node group.
Begin with one low-risk node or a representative non-production environment. Watch the old node cordon, each eviction, replacement scheduling, readiness, traffic recovery, and the PDB's allowed-disruption count. Continue only after the application returns to its expected healthy state. Do not overlap the node update with an application rollout unless both have been tested together and the combined unavailability has been budgeted.
After the update, confirm the intended node and Kubernetes versions, Ready replica counts, zone distribution, PDB status, application indicators, and absence of long-running Pending or Terminating pods. Capture any manual intervention and revise the PDB, probe, capacity plan, or runbook while the evidence is fresh. A successful drain is useful proof only for the conditions that were actually tested.
| Window | Action | Proceed when |
|---|---|---|
| T−30 | Freeze conflicting changes and capture baseline | Owners and stop conditions are confirmed |
| T−20 | Inspect PDB selectors, status, replicas, and placement | Protected workloads have safe disruption headroom |
| T−10 | Check scheduler capacity, events, probes, and monitoring | Replacements can schedule and become Ready |
| T−5 | Confirm node-group strategy and concurrency | Node and pod limits are compatible |
| T+0 | Start one controlled update step | Operator watches eviction through recovery |
Continue reading: A–Z business knowledge index · Amazon EKS Auto Mode explained
Frequently asked questions
Does a Pod Disruption Budget prevent EKS downtime?
It reduces the risk from voluntary evictions by limiting how many selected pods may be unavailable, but it cannot guarantee uptime. The workload also needs enough replicas, accurate readiness, topology spread, graceful termination, spare capacity, and monitoring. PDBs cannot prevent involuntary failures such as a node crash.
Can a PDB block an EKS managed node-group update?
Yes. If an eviction would violate the budget, EKS cannot complete the drain. AWS documents that a managed node update can fail with PodEvictionFailure when pods do not leave within 15 minutes and the update is not forced. Diagnose health, capacity, selectors, overlapping budgets, and tolerations before considering force.
Should I use minAvailable or maxUnavailable?
Use one, not both. maxUnavailable is often easier for a scalable Deployment because it expresses tolerated disruption relative to the controller's desired replicas. minAvailable is useful when the application must preserve a known healthy count, such as quorum. Calculate percentage rounding at every expected scale.
What PDB should I use for a single-replica workload?
A strict PDB can block voluntary eviction but cannot make one replica highly available. If the service must remain available during maintenance, add and safely spread another replica. Otherwise, document the downtime window and the procedure for temporarily changing the budget with the workload owner's approval.